-
Compressing Neural Networks Without Looking Inside Them
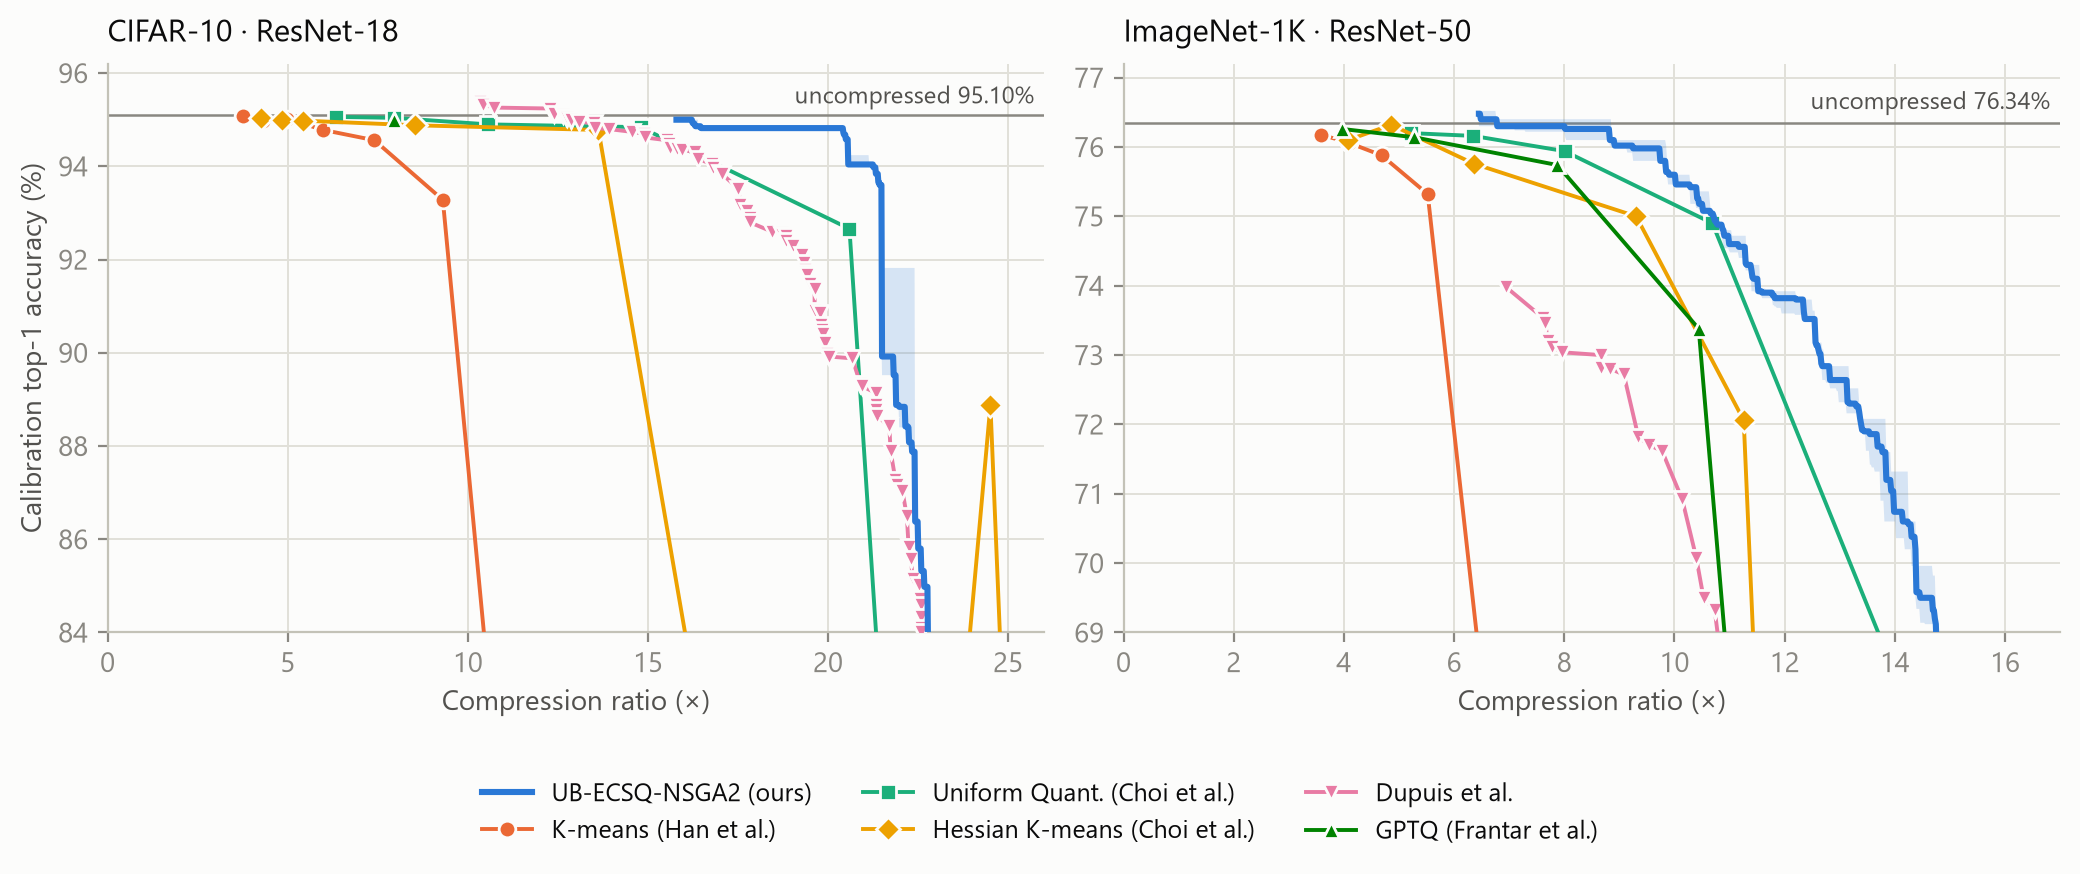
Our IEEE Transactions on Big Data paper shares one codebook across every weight of a pretrained network, merges it with an exact dynamic program, and searches just two numbers. Along the way, the number of codewords turns out to be the wrong thing to minimize.
-
Why Bigger Neural Networks Can Be Easier to Train
Bigger networks do not only represent more functions. Overparameterization can make gradient descent's job easier and leave surprising traces of initialization behind.
-
Gradient Descent's Hidden Tax: Rethinking How We Compare It to Gradient-Free Methods
Every GD step costs roughly 3× a gradient-free forward pass, so matching step counts isn't a fair benchmark. Match on FLOPs instead.
-
CurveBench: how neural networks learn curves
Watching MLPs learn 1D curves. Width, optimizer, and activation change what the prediction looks like as training unfolds.
